Devpost
Participate in our public hackathons
Devpost for Teams
Access your company's private hackathons
Grow your developer ecosystem and promote your platform
Drive innovation, collaboration, and retention within your organization
By use case
Blog
Insights into hackathon planning and participation
Customer stories
Inspiration from peers and other industry leaders
Planning guides
Best practices for planning online and in-person hackathons
Webinars & events
Upcoming events and on-demand recordings
Help desk
Common questions and support documentation
We ported a per-tenant AI workspace (local embed, STT, vector memory) to Arm64 and measured it honestly on three clouds. Arm cost and CPU wins depend on your vendor and silicon - not one simple story.
Probes your Arm CPU (NEON, i8mm, SME2), auto-tunes llama.cpp with honest statistics, and proves it: +82–144% faster LLM generation under real-world load — with machine-recorded receipts.
Compare Arm64 inference configurations with reproducible benchmark reports.
A banking-support triage app that switches its connected gateway to an optimized Graviton service only after checking speed, quality, and the exact release identity.
Watch one folding demo → a judge-gated sim loop amplifies it into 350 training episodes with zero teleoperation → a 21.4M ACT policy folds towels on dual SO-101 arms, verified on Arm64 every push.
Lightweight AI optimization for Arm edge devices using TensorFlow Lite.
Quantizing to int8 on Arm costs 65% of your throughput. We measured why, then built the kernel that fixes it: 9.1x faster than the fastest working FAISS int8 mode, at better recall.
Open-source Mobile AI engine accelerating on-device LLM inference on ARM laptops using Arm KleidiAI vector kernels & speculative decoding. 100% offline & private with upto +82% throughput boost.
Clusius doesn't just suggest migrating to Arm — it migrates, self-optimizes, and proves it live on real hardware: 4x the throughput, 1/4 the cost, zero mocked numbers.
A diagnostic tool that catches llama.cpp -fa auto silently picking the slower flash-attention setting on Arm CPU
An autonomous AI optimization platform for Arm that profiles, benchmarks, and continuously improves AI models and inference pipelines for faster, smaller, and more efficient deployment
Evidence before confidence: private migration assurance with a quality-gated local model and confirmed KleidiAI speedup on native Arm64.
Offline acoustic machine-health monitoring on an Arm CPU. FP32 to INT8: 4.07x faster in the deployed path, 3.68x smaller, accuracy retained — and the negative results are published too.
Four command-line tools that prove a model optimisation actually did something — or that it did not. Built and measured on an Arm laptop, 8 GB, CPU only.
One kilobyteor RAM, this is less then a single tweet. Zero floating-point ops. Glider-AI run a genuine neuronal network on the smallest ARM core and it just told my toy glider if did a barrel roll.
Approval-first infrastructure planning grounded in governed metadata and durable decision memory.
An Arm-optimized Edge AI goalkeeper that uses touch vector mechanics and Magnus effect physics to predict 9-zone shots with <1ms latency on entry-level mobile devices.
Optimizing a Hugging Face sentiment analysis model with ONNX Runtime for efficient performance on Arm architecture.
Lens AI: Your personalized AI guide for safer, smarter digital citizenship.
Build, iterate and optimize Mobile AI Apps with on-device models.
xxx
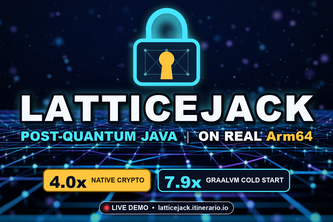
Real post-quantum TLS migration for Java, tuned for Arm64 — with a live demo judges can trigger themselves on real Azure hardware, not a recording.
Real-time Industrial Automation + Worker Safety powered by Arm Edge AI. 3D Digital Twin with 11.7ms inference, PLC control, and PPE detection.
Analyze, optimize, benchmark, and prepare AI models for efficient deployment on Arm-based cloud infrastructure with intelligent backend recommendations and automated optimization.
217 – 240 of 333