Devpost
Participate in our public hackathons
Devpost for Teams
Access your company's private hackathons
Grow your developer ecosystem and promote your platform
Drive innovation, collaboration, and retention within your organization
By use case
Blog
Insights into hackathon planning and participation
Customer stories
Inspiration from peers and other industry leaders
Planning guides
Best practices for planning online and in-person hackathons
Webinars & events
Upcoming events and on-demand recordings
Help desk
Common questions and support documentation
AQIntel turns air-quality data into hyperlocal insights that explain pollution, predict risks, and help cities take smarter, faster action.
MotionKey lets you teach your phone custom hand gestures, train a tiny personalized model on Arm64, and use those gestures to control the phone offline.
CAMRA uses Edge AI to detect road anomalies in real time, assess their risk using contextual factors, and generate actionable insights for smarter road maintenance.
Measure AI inference on real Arm64, compare execution strategies, and choose optimizations from reproducible evidence—not assumptions.
A 74.72% smaller, privacy-first INT8 action router that keeps sensitive AI-agent decisions on Arm64 devices.
Quantization-aware training makes a 2-bit Qwen3-0.6B usable on an Arm phone, delivering 12x lower perplexity than post-training quantization at a closely matched footprint.
AI SCADA for Floating City. 77% faster on Arm Cortex-M
YOLOX detection and a control policy on a Raspberry Pi 5, measured with the clock pinned. The policy drops from a 3.5 MB Transformer to 75 KB of NEON: 4777 us to 3.67 us on one core.
An AI interview coach that simulates technical interviews, evaluates responses, and provides personalized feedback for career success.
On-device visual memory for the things you leave behind.
Arm-optimized offline AI for frontline healthcare, cutting on-device voice inference by 53.8% while maintaining our 100/100 benchmark quality gate.
Portable Arm AI builds ship with the matrix unit off: 5.75x slower prefill on a Neoverse N2 cloud CPU. coldpath audits any shipped binary, caught the top offender (Ollama), and gates it in CI.
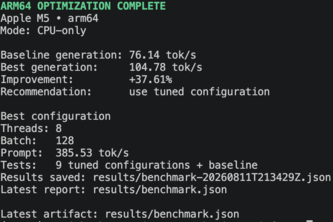
Auto-tune llama.cpp for your Arm64 cloud instance — because the fastest quant format depends on the hardware, not the model.
ArmInfer automatically benchmarks and tunes llama.cpp inference on Arm64 hardware, then reports the fastest measured configuration with reproducible before/after results.
100% offline code review on Apple Silicon reads real code diffs, reviews them via MLX on-device, and flags any finding it can't verify against your actual code. No code ever leaves your machine
One model load, scene-by-scene Qwen3-TTS: 38.4% less wall time on Apple M4 with bit-identical WAVs.
Autonomous AI agent that analyzes ML models, applies INT8 quantization for Arm64, and generates optimized deployment packages with measurable 4x size reduction and 3x speedup.
Action recognition in video can be optimized by perforation with dendrites. We optimize a r2plus1d_18 model with 2 dendrites, reducing error by 10% with negligible impact on speed.
An ultra-lightweight TinyML gesture and voice command controller optimized for Arm architectures with sub-10ms latency and 100% offline edge processing.
son of Anton SV
llama.cpp defaults to every core on Android - the worst choice on big.LITTLE. LITTLETai reads your CPU layout and picks the right flags. 2.2-11x faster decode, up to 11x less energy. No patch.
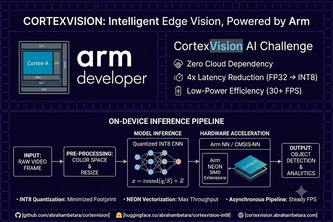
CortexVision: Intelligent edge vision, powered by Arm.
On-device relational AI infrastructure—enabling everyone to have an AI companion that truly understands them, is always by their side, and is theirs to fully own.
169 – 192 of 333