Devpost
Participate in our public hackathons
Devpost for Teams
Access your company's private hackathons
Grow your developer ecosystem and promote your platform
Drive innovation, collaboration, and retention within your organization
By use case
Blog
Insights into hackathon planning and participation
Customer stories
Inspiration from peers and other industry leaders
Planning guides
Best practices for planning online and in-person hackathons
Webinars & events
Upcoming events and on-demand recordings
Help desk
Common questions and support documentation
Mobile AI Track: Runs within a 100 MB RAM boundary on any ARM CPU, utilizes NEON for SIMD instructions, and mmapped to operate within 60 MB peaks per layer. Fully featured+actual use Cases, not a toy.
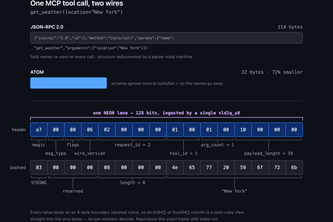
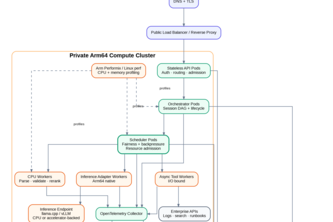
Most optimize the model. We optimized the wire: a binary, NEON-aligned format for MCP tool calls. ~12× more agent-turns per Neoverse core, 44% fewer bytes, confirmed on Arm Performix counters.
A 316 MiB speech model that transcribes, timestamps, and separates speakers entirely on-device, with hand-written Arm NEON kernels for every precision in the package.
A 1-trillion-parameter AI engineer that reviews your PRs and fixes bugs overnight — on Arm CPUs, no GPU on Earth involved. ~$1/hour on Azure Cobalt, and your code never leaves your tenant.
ARM-Aware Scheduling and agentic harness for On-Device LLMs
Energy optimization for ML/AI workloads for ARM cloud servers
A standardized, reproducible platform for benchmarking AI inference performance across Arm-based (and x86) cloud infrastructure.
An open-source Physical AI toolkit that converts simulated robot perception into explainable navigation decisions and prepares ONNX models for efficient Arm64 edge deployment.
Self-calibrating llama.cpp serving for Arm CPUs. Probes memory bandwidth, sizes the deployment from the GGUF header, auto-finds the latency knee under open-loop load.
PlaneFuse makes on-device camera AI faster by letting a vision model work directly from camera data instead of first building a full RGB image.
Varaha AI offloads INT8 Swift-YOLO to the Arm Ethos-U55 NPU for 100% accelerated boar detection in 198KiB SRAM, triggering real-time deterrence and alerts via an off-grid LoRa mesh network.
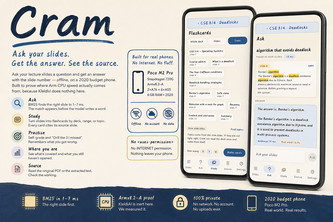
Ask your lecture slides a question and get an answer with the slide number — offline, on a 2020 budget phone. 3x faster to first word, and none of it came from Arm's KleidiAI. We measured.
Load-time compiler and runtime for efficient low-bit SME2 inference
EdgeTuner searches the ideal way to run your model on a Raspberry Pi 5. Quantization, graph optimization, memory arena, and threads are all measured and optimized for Raspberry Pi.
A private AI assistant running Gemma 4 entirely on your Arm phone: voice, vision, live face recognition, and hands-free skills like directions, alarms, and reminders, with nothing sent to a server.
Flood simulation, accessible routing, and grounded AI guidance, entirely offline, on an $80 Raspberry Pi 5.
Run 30B AI locally on a phone by streaming only the experts it needs
DelegateDoctor finds the ExecuTorch/XNNPACK fallback actually slowing your Arm model, applies proven repairs, and keeps them only if a real Android phone proves they are correct and faster.
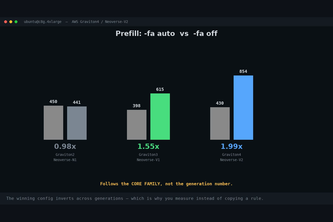
Measure the Arm machine you're actually on. GraviTune found that llama.cpp's default setting costs 2x prefill throughput on AWS Graviton4 proven with hardware counters and filed upstream.
Keep the AI hungry !!
FLOPs lie about energy — memory access costs ~100× more than compute. Joulehound measures what AI agents actually burn on Arm silicon, proving the NEXUS metric tracks real joules while FLOPs don't.
Unlock capabilities of current and future silicon with 1 tool instead of ±5.
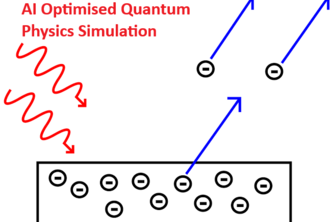
A portable, high efficiency photoelectric effect simulator for research purposes. Matches the Physical AI Track
AI endpoint that decides when developer's task should run on-device and when it needs to be sent to cloud.
1 – 24 of 333