Devpost
Participate in our public hackathons
Devpost for Teams
Access your company's private hackathons
Grow your developer ecosystem and promote your platform
Drive innovation, collaboration, and retention within your organization
By use case
Blog
Insights into hackathon planning and participation
Customer stories
Inspiration from peers and other industry leaders
Planning guides
Best practices for planning online and in-person hackathons
Webinars & events
Upcoming events and on-demand recordings
Help desk
Common questions and support documentation
ArmFlux Studio automatically profiles, optimizes, and benchmarks AI models for Arm—finding the best configuration for speed, efficiency, and accuracy.
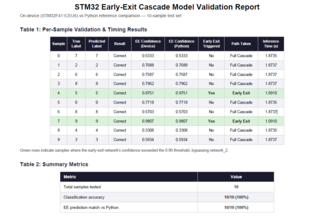
Early-Exit KWS: Adaptive CNN Inference for Faster, Resource-Efficient Keyword Spotting on Arm Cortex-M4.
Pocket Proof transcribes audio privately on Arm devices—no uploads. Its verified optimization makes Whisper 1.55× faster, 70% smaller, and use 44% less memory. Local AI, with receipts.
Quantum Physics - uses the digital measure which Which General Relativity now confirms with analog in tandem use case for storage giving a instant recall for agents to utilize with in 3 bytes code
Cost/SLO-aware LLM serving optimizer for AWS Graviton4 (Arm Neoverse V2) with continuous batching, KleidiAI INT4, Arm Performix PMU hardware proof, SHA-256 ledger, and MCP tool interface.
LLM inference for the other 6 billion. No GPU. No cloud. Just ARM.
Benchmarking energy-efficient vision-language model inference across Arm edge platforms, comparing CPU, NPU, and GPU acceleration for performance, power, and thermal efficiency.
Transforms any Arm-powered mobile device into an intelligent, on-device AI agent that perceives, plans, and executes complex tasks autonomously, delivering real-time automation with no cloud reliance.
Running an LLM on a new machine is usually guesswork. LMFit changes that by making model selection hardware-aware and benchmark-driven — specifically for ARM systems.
Full-Stack Physical AI Optimization on RA8P1: INT8, Vela, Ethos-U55 and RTOS Parallelism
Private AI meeting notes, transcription, and action items on your iPhone.
Motion-gated person detection on Arm Cortex-M: a three-level attention cascade that spends inference compute only when, and where, something moves. 98-99% of inferences skipped, measured on hardware.
Find out which Arm CPU path your AI inference actually took — and what it cost in joules per token.
On-device gesture control system, optimized end-to-end for Arm architecture.
Arm64-optimized financial AI that profiles, benchmarks, and accelerates document intelligence for efficient cloud inference.
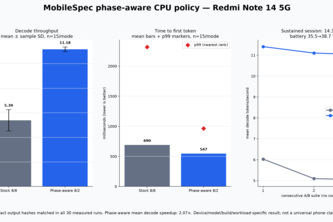
Phase-Aware CPU thread autotuning for llama.cpp on Arm Android. Solves big.LITTLE barrier lock contention to deliver a verified 2.07x sustained decode speedup and 9.4x latency stability.
NEURA AI is an cloud based Arm-optimized cognitive AI operating system that remembers, reasons, and automates workflows across devices with secure on-device intelligence.
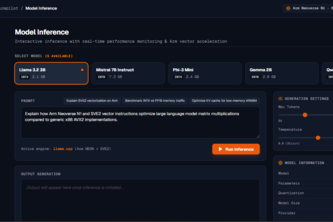
ARM64-first AI inference platform to benchmark models, analyze performance, optimize runtime configurations, and generate actionable recommendations for efficient deployment.
Offline-first Physical AI for Arm64 that intelligently orchestrates wildfire, earthquake, flood, and landslide monitoring on a single constrained edge node.
Private on-device AI file search for Android on Arm
AfyaAI is an AI-powered health assistant that provides accessible, reliable, and personalized health guidance anytime, anywhere.
Real-time speech translation that runs entirely on your Arm-powered device. No cloud, no signal, no compromise. Speak freely, anywhere.
Momentum is an energy-aware workload navigator that turns student overwhelm into one clear, achievable next step—privately, explainably, and offline.
Which kernel path is your GGUF actually on?
25 – 48 of 333