Devpost
Participate in our public hackathons
Devpost for Teams
Access your company's private hackathons
Grow your developer ecosystem and promote your platform
Drive innovation, collaboration, and retention within your organization
By use case
Blog
Insights into hackathon planning and participation
Customer stories
Inspiration from peers and other industry leaders
Planning guides
Best practices for planning online and in-person hackathons
Webinars & events
Upcoming events and on-demand recordings
Help desk
Common questions and support documentation
A bespoke home power management system built on a Raspberry Pi Zero W which uses ML to predict solar generation, then calculates and schedules battery and EV charging around an energy tariff window.
This project involved developing and benchmarking 3 improved ARM kernels for Gated Delta Net, a linear-complexity replacement for transformers used in the latest Qwen, Nemotron and Kimi models.
On-device AI for smarter, battery-aware lost-device recovery on Arm Android.
ARMEdge intelligently routes AI workloads between local Phi-3 and cloud Gemini based on device, battery, CPU, memory, network, and workload conditions for efficient inference.
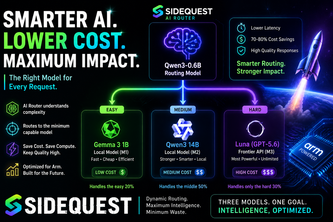
Not every question needs a supercomputer. SideQuest intelligently routes each request to the right AI model - saving compute and cost without sacrificing intelligence when it matters.
AI that spots pedestrians crossing and alerts the vehicle in milliseconds.
A production-ready inference control plane that securely routes, benchmarks, and manages llama.cpp models across local GPUs and Google Axion Arm64 workers.
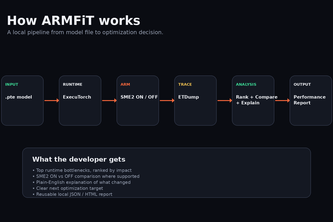
ArmFit turns raw ExecuTorch profiler output into a plain-English performance report, ranks your model’s bottlenecks, measures/projects Arm’s SME2 impact, and tells you exactly what to optimize next.
ArmTune Serve measures how an LLM Model actually behaves on your exact Arm64 machine, then hands you the deployment command.
I just asked 'why not?', that's it
ArmTune autotunes llama.cpp on Arm64—searching threads, batch, and KV-cache settings—then ranks configs by tokens/sec and TTFT with reproducible before/after reports.
Offline bidirectional English-Hindi speech to speech translation, entirely on-device. We rebuilt the model's decoder to actually cache 2x faster, on Arm CPUs from budget phones to flagships.
Empowering first responders with a zero-trust autonomous drone swarm. We use local AI, YOLOv10, and live WebRTC to detect fires, floods, and survivors in real time.
AdaptiveAI is an edge-AI road safety system that uses YOLO object detection and dynamically chooses mobile or cloud processing based on network conditions, device workload, and AI confidence.
AI that knows when to spend bits—and when to save them. Precision Governor switches live between Full, Balanced, and Eco models as battery and heat change, keeping on-device vision running.
Check out ArmPi4! We optimized a model architecture so the Raspberry Pi 4's performance is 3-4x better at finding PCB defects. We even show Interactive hardware stats using Grafana and Prometheus.
The reflex arc for embedded robots on Arm: sensor to brake signal, worst-frame latency cut 2.3x, with every speed claim paying its accuracy bill against perfect simulator ground truth.
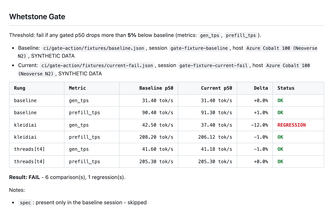
Arm's recommended fast path triples generation latency on an M1 Max and speeds up two cloud chips. Whetstone is the instrument that catches it
Performix is an AI performance platform that detects CPU bottlenecks, generates safe optimizations, validates execution, and measures real runtime and memory improvements.
Record linkage when two datasets share no join key. Four matchers, token overlap to quantized neural, measured on identical data, so you know what accuracy actually costs on the machine at hand.
Autonomously optimizes LLM inference across quantization, CPU threads, and context size to find the fastest, most efficient configuration for edge deployment.
On-device PII redaction for Arm: a from-scratch int8 transformer in C with five hand-written AArch64 kernel tiers and runtime dispatch that never picks an instruction your silicon can't execute.
Track 2: Cloud AI, 63.8% higher throughput, 92.7% less context waste, 95% lower cost per agent task on Arm Neoverse — with zero GPU.
Hear the machine before it stops — locally on Arm.
49 – 72 of 333