Devpost
Participate in our public hackathons
Devpost for Teams
Access your company's private hackathons
Grow your developer ecosystem and promote your platform
Drive innovation, collaboration, and retention within your organization
By use case
Blog
Insights into hackathon planning and participation
Customer stories
Inspiration from peers and other industry leaders
Planning guides
Best practices for planning online and in-person hackathons
Webinars & events
Upcoming events and on-demand recordings
Help desk
Common questions and support documentation
Audimus detects scam calls from the words spoken, entirely on-device with Gemma 4 E2B. No server, no data leaving your phone, 12.6x faster with Arm KleidiAI.
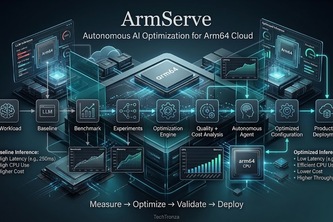
**ArmInferX — Autonomous AI inference optimization for faster, smarter, and more cost-efficient Arm64 cloud deployments.**
Survival Signal: AI triage for crisis zones. It turns symptoms into urgent data to prioritize care when hospitals are overwhelmed. Resilience through instant AI diagnostics.
A pure C++ LLM inference server optimized for Armv9-A cloud instances. Leverages KleidiAI for maximum performance, exposing a lightweight, OpenAI-compatible REST API for GGUF models.
An ARM Cortex-M Physical AI system combining optimized AI crack detection and multi-sensor monitoring to generate adaptive health scores, component risk maps, and real-time maintenance decisions.
Simple native llama inference engine build with SKaiNET
BusinessRadar: AI scans Tashkent via OpenStreetMap & BigData to find 100% profit spots 🎯 Real-time stats on rivals & traffic 📊 Stop guessing, use AI to dominate the city! 🚀💸
Autonomous autopilot agent combining GPT-5.6 & Codex reasoning with tactical human augmentation. Automates resource acquisition and threat mapping inside a HUD.
OMNY-ANALYST: While others hallucinate, we automate. 12 months of compliance in 10 mins with Gemini 2.0. Scalable. Fast.
An AI that shrinks big language models until they run on an old phone — and lets the phone, not the AI, decide whether it worked.
llama.add removes attention work a model can afford to lose, making llama.cpp faster and lighter on Arm with no retraining, no new model file, and one runtime flag.
Benchmarks LLMs on real Android hardware to isolate Arm KleidiAI's true speedup from quantization alone; up to 2.4x faster inference, proven on a budget phone, not a flagship.
forsecurity
Sensitivity-aware mixed precision for ARM. Find the fragile tensors, spend bits there, and keep everything else small.
Bringing Mamba-3 from GPU kernels to Arm CPUs
Privacy-Preserving Activity Recognition with Real-Time Edge AI.
An AI optimization copilot that automatically profiles naive AI code kernels and refactors them into vectorized Arm NEON assembly and KleidiAI microkernels, with green-cloud sustainability metrics.
A quality-gated benchmark that chooses the right on-device AI configuration for the workload—not merely the fastest-looking one.
AI for good
One command to quantize and benchmark any Hugging Face model for Arm CPUs — real, reproducible before/after numbers verified on genuine Arm hardware, not marketing claims.
coSphere turns hazard classification into rover action
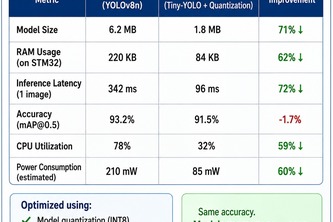
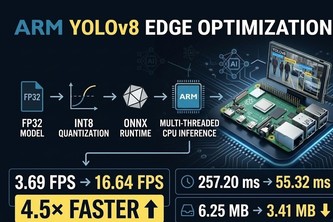
Optimizing YOLOv8 for faster and lighter AI inference on ARM-based edge hardware using INT8 quantization, ONNX Runtime, and multi-threaded CPU execution.
Most Edge AI wastes power running max accuracy nonstop! ARIA is a trained Meta-Controller that switches AI model variants on Arm Cortex-M chips in real time, spending compute when it really matters.
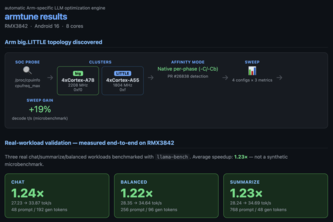
Auto-tunes llama.cpp on Android big.LITTLE: +23% decode, validated end-to-end. Found & fixed a 2-year silent affinity bug in llama.cpp, merged upstream https://github.com/ggml-org/llama.cpp/pull/26838
73 – 96 of 333