Devpost
Participate in our public hackathons
Devpost for Teams
Access your company's private hackathons
Grow your developer ecosystem and promote your platform
Drive innovation, collaboration, and retention within your organization
By use case
Blog
Insights into hackathon planning and participation
Customer stories
Inspiration from peers and other industry leaders
Planning guides
Best practices for planning online and in-person hackathons
Webinars & events
Upcoming events and on-demand recordings
Help desk
Common questions and support documentation
OmniGraph is a voice-driven, Generative UI data copilot that allows anyone to ask natural language questions about their datasets.
Turn natural-language AI policies into deterministic, nanosecond-scale Arm64 edge decisions.
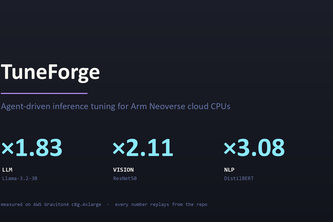
An agent that tunes AI inference on Arm cloud CPUs — and rejects its own wins when they cost accuracy. Up to ×3.08 measured on Graviton4; every recipe replays on your host.
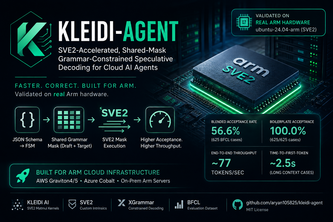
SVE2-accelerated shared-mask decoding that pushes agentic JSON tool-call acceptance to 100% on Arm64 — measured, not projected.
Arm isn't one target. A NEON kernel that flies on one chip can lose to scalar on the next. Vane picks the right kernel at runtime and can't print a number it didn't measure.
On-device ASR for Ghana's code-switched speech, compressed for Arm devices without losing the accuracy
An audit-ready profiler bridging Arm Neoverse Cloud LLM inference with dynamic grid energy telemetry via Arm Performix to measure vector pipe saturation, energy/token, and ISO/IEEE quality scores.
Sub-15ms on-device crop disease diagnosis using INT8 MobileNetV2 + Arm NEON SIMD. 98.3% accuracy, 9 diseases, bilingual English/Urdu guidance. Zero internet. Zero cloud. Runs entirely on Arm Cortex-A.
Edge posture AI on Kria KV260: proven YOLOv4 baseline, then YOLOv11 model surgery + INT8 for Arm DPU.
Interactive Arm AI benchmarking lab comparing baseline and optimised workloads across latency, throughput, memory, and model size, with SIMD experiments, optimisation analysis, web dashboard.
A reproducible Arm64 study of llama.cpp + KleidiAI on Android, measuring how Arm CPU optimizations affect prompt processing and token generation across LLM workloads.
On-device LLM inference scheduler for Android that prevents thermal throttling by dynamically hot-swapping quantization (INT4↔INT8), thread count & context length — keeping tokens/sec stable.
Optimize MobileNetV2 for faster, smaller inference across x86 and Arm, with automated benchmarking, cross-platform comparison, and deployment recommendations.
A brake reflex you can audit.
Your discharge papers, decoded on your phone in airplane mode. An Arm-optimized INT4 LLM gives you a plain-language summary, a jargon glossary, and questions to ask your doctor. Full Privacy.
Anchor is an automated Arm64 deployment pipeline that detects your hardware, benchmarks generic vs KleidiAI optimized builds across model and tells you exactly which configurations get faster.
UniEdge: Adaptive LLMs on Arm. Optimizing Gemma-3 via KleidiAI/NEON & local SQLite memory for 17% faster inference and offline continuous learning on resource-constrained edge devices
Accelerating ERNIE inference on AWS Graviton3 with ONNX Runtime, hardware-aware tuning, and INT8 quantization.
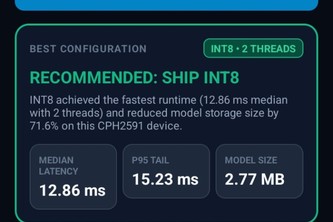
QuantForge benchmarks FP32 vs INT8 AI models on real Arm64 Android devices, auto-tunes CPU threads, and recommends the fastest deployable configuration instead of guessing.
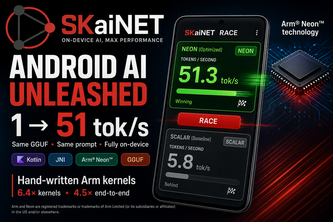
Hand-written Arm NEON kernels took Kotlin's AI framework from 1 to 51 tok/s on-device. A few lines of Kotlin. GGUF in => tokens out.
Low-rank model compression for ARM based CPU'S: 47.75% smaller, 1.4x faster on-device. I also built and rigorously falsified my own optimization hypothesis and show my work either way.
Multi-Objective Auto-Tuner for LLM Inference on Arm CPUs
A router-driven Qwen2.5 cascade on AWS Graviton4 that beats a self-hosted baseline by 20x and a hosted API by 4x — built with llama.cpp, KleidiAI kernels, and speculative decoding for Neoverse-V2
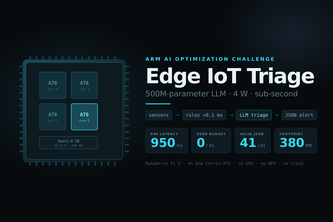
A 500M-parameter LLM triaging live sensor data on a $80 Raspberry Pi 5. Hybrid threshold+LLM pipeline holds p99 at 1,841ms with zero budget misses — 3.2x faster after systematic ARM optimization.
97 – 120 of 333