Devpost
Participate in our public hackathons
Devpost for Teams
Access your company's private hackathons
Grow your developer ecosystem and promote your platform
Drive innovation, collaboration, and retention within your organization
By use case
Blog
Insights into hackathon planning and participation
Customer stories
Inspiration from peers and other industry leaders
Planning guides
Best practices for planning online and in-person hackathons
Webinars & events
Upcoming events and on-demand recordings
Help desk
Common questions and support documentation
Local-first Physical AI that detects expected-vs-observed state deviations on Arm edge devices, combines deterministic safety rules with advisory AI, and keeps sensitive data offline.
Closed-loop Physical AI on Arm — sense, plan, act — with 33× INT8 GEMM vs scalar.
Autonomous AI reasoning optimization lab that autotunes and verifies the fastest correct execution path on Arm64.
InferPerf gives Arm engineers a clear view of why AI workloads slow down - using PMU‑driven microarchitectural profiling to expose bottlenecks and unlock faster, more efficient inference.
Saves 90% power & cost by routing simple prompts to an Arm-optimized local model (NEON/SVE), escalating to Fireworks Cloud only when complex reasoning is needed.
Lingot turns untuned LLMs into faster, cheaper, quality-validated deployments optimized for Arm cloud CPUs.
aarch64 vs x86 inference on cloud compute to test which is better
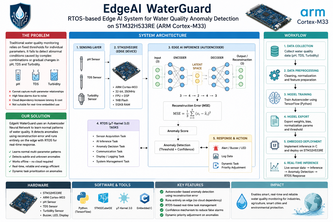
An RTOS-based Edge AI system that runs an autoencoder directly on an STM32 to detect abnormal water quality from pH, TDS, and turbidity in real time.
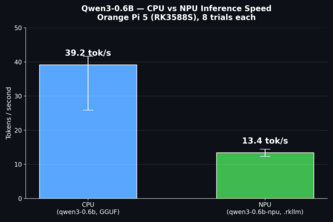
A real grow-cabinet monitors soil moisture and narrates plant health using a local LLM on the Orange Pi 5's NPU — with a measured CPU vs. NPU benchmark showing exactly where NPU inference pays off.
Analyses, Bencharks and Optimize the best AI model to deploy on ARM based Edge Devices
Verify whether llama.cpp on Arm actually uses KleidiAI kernels—and measure what that costs on Google Axion.
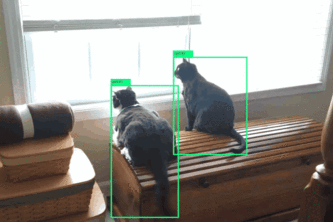
An offline real-time walking-hazard alert system for visually impaired users on Raspberry Pi 4, powered by Arm INT8 quantization & XNNPACK acceleration for 3.76x speedup & 28.9ms latency.
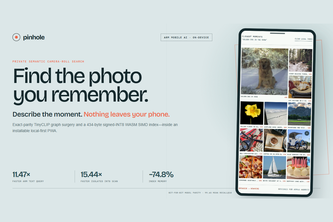
Find any photo from a natural-language memory—privately on-device. Pinhole combines exact-parity TinyCLIP graph splitting, compact INT8 vectors, and a 434-byte Arm-optimized WASM SIMD kernel.
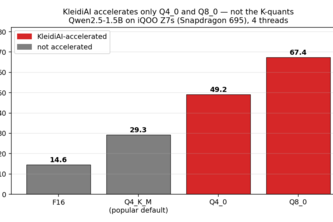
An agent that tunes LLM quantization layer-by-layer to your Arm device — and, along the way, measured exactly what Arm's missing K-quant kernel costs.
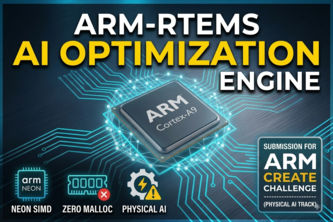
Real-time predictive maintenance on Arm Cortex-A9 / RTEMS 7 with 0 bytes dynamic memory allocation, NEON SIMD acceleration, and C11 memory bounds protection.
Ship a task, not another model: byte-exact quantized updates for adaptive Physical AI on Arm. 12.4 MB instead of 352.2 MB, verified on Raspberry Pi 5.
An offline evidence-gap checker whose optimization claims ship with reproducible native Arm64 receipts.
Memory of the Utopia™ — On-Device AI Vault That Can't Be Jacked. 4x faster, 100% local, Arm-optimized.
Smarter Machines. Safer Labs. Powered by Arm Edge AI.
Shallow River is a optimized C++ alternative to NVIDIA Deep Stream on Jetson Orin Nano that enables CPU and GPU native libraries concurrently without expensive memory copies using unified memory.
Running local LLMs and agentic AI on single board computers.
SUVI puts image and language tokens in one stream, removing the always-on vision towers. Further, on Arm, 1 KB FSQ caching and eight-core scaling cut memory 25.9% and latency 30.3% versus LLaVA.
Native, offline-first gait analysis for Arm devices with XNNPACK CPU A/B benchmark.
On-device acoustic intelligence for post-harvest loss prevention.
145 – 168 of 333