Devpost
Participate in our public hackathons
Devpost for Teams
Access your company's private hackathons
Grow your developer ecosystem and promote your platform
Drive innovation, collaboration, and retention within your organization
By use case
Blog
Insights into hackathon planning and participation
Customer stories
Inspiration from peers and other industry leaders
Planning guides
Best practices for planning online and in-person hackathons
Webinars & events
Upcoming events and on-demand recordings
Help desk
Common questions and support documentation
Speak your ideas. STICK builds the presentation.
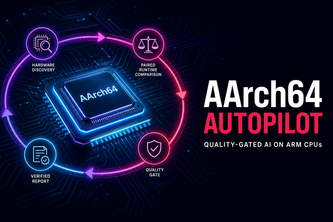
Give it an Arm64 machine and an agent workload; it discovers a fast quality-preserving CPU configuration and generates the proof.
A64Forge benchmarks every AI agent stage on Arm64, protects quality, and compiles faster, lower memory model routing backed by verifiable evidence.
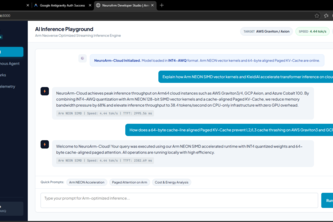
An Arm64-optimized AI inference engine that delivers faster, leaner cloud LLM inference with NEON, INT4 quantization, KV-cache optimization, NUMA scheduling, and autonomous MCP agents.
Adaptive, deadline-aware AI inference for Arm64 robots—PerceptShift profiles, certifies, and switches optimized ONNX Runtime execution profiles at runtime.
Edge AI-powered real-time threat detection on Renesas EK-RA8P1 using Arm Ethos-U55, detecting guns and knives with optimized on-device inference and instant alerts.
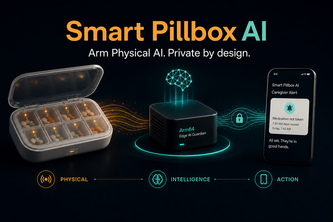
Smart Pillbox AI turns pillbox sensor events into private, offline safety actions using an INT8 Arm64/NEON inference kernel—34× faster with 75% less model memory.
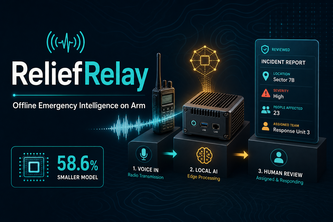
Offline voice intelligence for emergency teams—turning noisy radio reports into reviewed, prioritized incidents on local Arm hardware, even when connectivity fails.
An end-to-end NLP inference optimization and benchmarking suite evaluating DistilBERT across native Arm64 and x86_64 architectures.
AEOLUS simulates a space habitat's air system to spot faults like a broken fan early, before the air gets unsafe. Every run is repeatable, so the results can always be trusted and checked.
MozhiAI is the first open-source offline multilingual voice AI platform for Indian languages (Tamil, Hindi, Telugu) optimized for Arm64 hardware.
Real-time, camera-based 3D drone localization optimized for Arm edge hardware, combining AI and classical vision for GPS-denied autonomous flight.
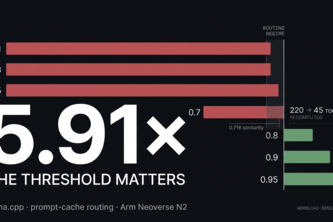
Four users of one AI agent cost 10.9× time-to-first-token on Arm Neoverse N2. One flag fixes it. We swept 6 prompt shapes to find exactly when it matters — and when the flag does nothing at all.
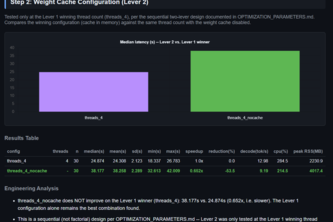
Local Gemma 4 on a Pixel 7, transforming Arm/CPU docs into Frenglish arrow-schemas, while we measure whether thread-count tuning actually moves latency on Tensor G2's heterogeneous cores.
Speed is nothing without control. To optimise for low latency alone misses the most important part of Physical Ai: correctness. I reduce VLM from ~4Sec. to 33ms gesture input + 500ms per. observation.
The ultimate AI routing layer. NEOVERSE leverages KleidiAI micro-kernels to run LLM workloads natively on Arm infrastructure, eliminating cloud compute waste with zero latency.
Evidence-first console for measuring, evaluating, and optimizing LLM inference on Arm64 hardware.
Optimize and benchmark real AI models for Arm64 — with every number labeled real or simulated, never faked.
BioLoop Edge ARM Optimized is an Arm-native physical-AI digital twin for preserving biological specimens during transport.
An AI-driven cache optimization system that analyzes memory access patterns and intelligently selects cache configurations and replacement strategies to improve performance and reduce cache misses.
Know yourself just a little bit more!
AAPO is an AI-agent performance optimization platform that acts as a smart middleware layer between applications and AI models. It focuses on secure requests, performance monitoring, optimization.
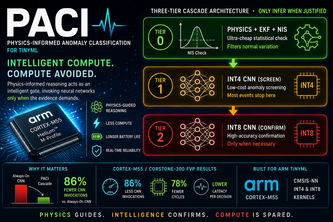
PACI cuts TinyML compute by 90.58% (10.62× speedup) on Arm Cortex-M via ~465 ns physics-EKF gating and CMSIS-NN INT4/INT8 cascade inference while preserving full reference classification parity.
An AI platform that optimizes prompts, routes requests to the best LLM, reduces AI costs, and provides real-time analytics.
121 – 144 of 333